Description
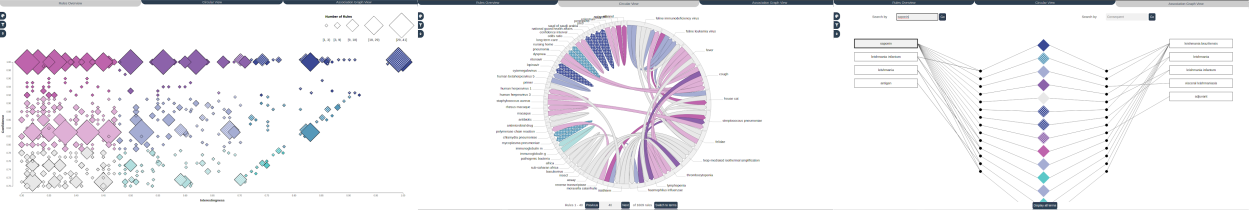
ARViz is a visualization dashboard that supports interactive browsing of association rules through three synchronized and complementary visualization techniques:
- Overview of Rules: We use a scatter plot technique with a slight modification to allow the user to identify how many rules are concerned by each pair <confidence, interestingness>. The chart's x-axis represents values of interestingness, while the y-axis represents values of confidence. The crossing points between both measures are represented by diamond symbols, which color encodes measures of interest, texture encodes symmetry, and size encodes the number of rules for each pair of values <confidence, interestingness>.
- Circular Paginated View of Subsets: We use a chord diagram chart to provide a clear and simultaneous representation of relationships between items and their measures of interest. The arcs correspond to single items and the ribbons represent the rules, which color encodes values of confidence and interestingness, and texture encodes symmetry. Each ribbon contains arrowheads on its extremities to indicate the rule's direction, i.e. the extremity containing the arrow implies that the item is a consequent. The order of arcs around the circumference can be modified by sorting the keywords by alphabetic order or according to the number of association rules involving each item.
- Exploratory Graph View of Items: The association graph is meant to give an intuitive portray of antecedent and consequent items involved in rules by representing them as nodes placed in the left and right side of rules. We use an association graph with two vertical stacks of labeled rectangles at the left and right extremities of the window to represent items, and diamond-shaped nodes placed at the center of the visualization space to represent the association rules between items.
Association Rules Mining Algorithm
Input data
A CSV file containing a table which rows represent the transactions (e.g. scientific publications) and columns represent the items (e.g., keywords in the publications). The input dataset is then pre-processed and transformed into a transaction matrix, which intersection cells contain binary values indicating whether the item exist on the transaction (1) or not (0).
The algorithm
The main goal of the algorithm is to derive association rules between named entities. As an illustrative example, let us take the named entity
coronavirus, which in 70% of cases where the term was found in a publication, one would also find to the named entity
China.
We use the
FP-Growth algorithm from the Python library
mlxtend.frequent_pattern, created by
Sebastian Raschka.
Output data
The output data (represented in the visualization) consists of a table which rows correspond to rules and the columns contain descriptive variables, defined as follows:
- Antecedents: either a named entity or a pair of named entities.
- Consequents: either a named entity or a pair of named entities, which are consequence of the existence of antecendents in the publication.
- Support: the probability of finding the named entities X and Y in a transaction. It is estimated by the number of times X and Y appear among all available transactions. The resulting value is between 0 and 1.
Supp(X → Y) = P(X ∩ Y)
- Confidence: the probability of finding the named entity Y in a transaction, knowing that the named entity X is in the same transaction. It is estimated by the corresponding frequency observed (number of times that X and Y appear among all transactions divided by the number of times where X is found). The resulting value is is between 0 and 1.
Conf(X → Y) = P (Y / X) = P(X ∩ Y) / P(X) = Sup(X → Y) / Sup(X)
- Interestingness: the serendipity of the rule, which serve to penalize the rules or named entities with high frequency of appearance within the database.
Interestingness(X → Y) = (Supp(X → Y) / Supp(X)) × (Supp(X → Y) / Supp(Y)) × (1 - (Supp(X → Y) / Tot. No. of transactions))
- isSymmetric: whether the rule works inversely, i.e. whether there is another rule where the antecendent is the consequent and vice versa.
- Cluster: the cluster which the rule belongs. These are automatically generated with no assigend semantic meaning.
Furthermore, to keep only non-evident rules, we applied filtering methods based on:
- the confidence, which defines a threshold of confidence (≥ .7) that determine whether the rule is kept.
- the interestingness, which defines a threshold of interestingness (≥ .3) that determine whether the rule is kept.
- the redundancy, which remove every rule that comply with the following definition of redundancy: A,B,C → D is redundant if Conf(A,B → D) ≥ Conf(A,B,C → D)